Hackaday · Creativity & design
Running Large Language Models on Older Hardware
It's possible to run flagship Large Language Models (LLMs) on older, GPU-less servers, though with significant speed limitations.
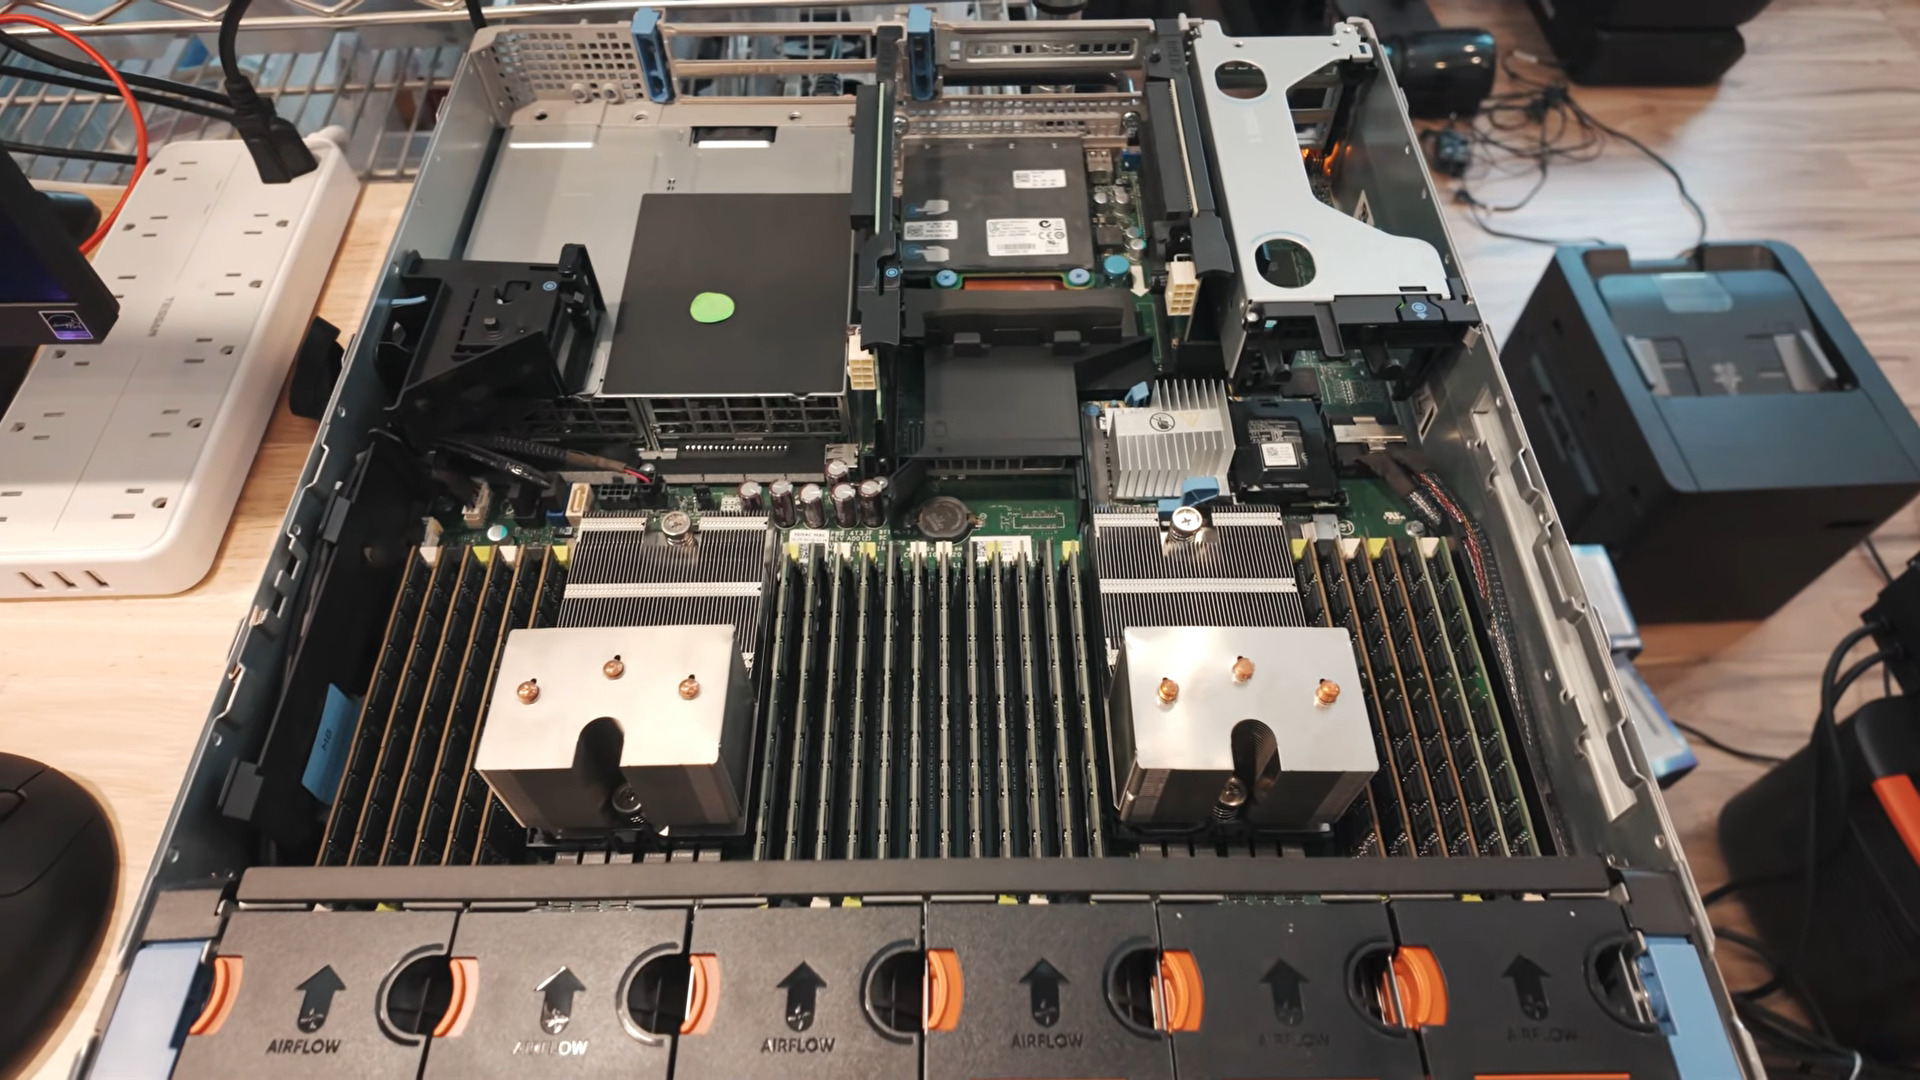
A 14-year-old Dell PowerEdge R720 server, equipped with 348 GB of DDR3 system memory and twin Xeon processors, was used to run LLMs like GLM 5.3 Flash, Qwen 3.8 Flash, and Qwen 3.8 27B without any GPUs.
The primary limitation is speed, with the server achieving a maximum of four tokens per second. This is attributed to the limited 20 threads available from the processors and the lack of modern instruction sets.
Despite the slow performance, the author suggests that batch-processing workloads at this speed could still be useful for certain applications.
The hardware used is relatively inexpensive on the second-hand market, estimated at around $600.
While future optimizations might improve speeds, real-time conversational performance is not expected. This approach is presented as an alternative to smaller models on less powerful devices.
AI-samenvatting op basis van de bron.
Hackaday